The Ultimate AI Showdown: Is GPT 5.3 Codex Or Claude Opus 4.6 The New King Of Code?
Nov 02, 2026

Choosing the right tool for your engineering stack shouldn’t be a gamble.
Whether you’re choosing between GPT 5.3 Codex vs Claude Opus 4.6, you want to know:
In our testing, we used both models in production environments with real software codebases.
We tasked them with real-world work such as back-end refactoring, creative website development, and terminal-based operations.
We found that these two models shouldn’t be seen as competitors but as two different engineering roles within your team.
| Feature / Core Attribute | Claude Opus 4.6 | GPT-5.3 Codex |
| Primary Engineering Role | Senior Technical Architect | Hyperproductive Coding Intern |
| Standard Context Window | 200K Tokens (1M Token Beta Available) | Repo-RAG Focused / Targeted Files |
| Terminal Bench 2.0 Score | 65.4% | 77.3% |
| Input Token Pricing (per M) | $5.00 | Highly Discounted Base |
| Output Token Pricing (per M) | $25.00 | Highly Economical Alternative |
| Best Suited For | Greenfield architecture, complex refactoring | Fast iteration loops, rapid unit tests |
Claude Opus 4.6 has strong capabilities for handling structural ambiguities.
It will pause to understand how multiple modules interact through an adaptive thinking process before writing any syntax.
Firstly, it can handle large changes within the repository due to its large context window:
Secondly, it is perfect for managing complex greenfield projects, refactoring, and tracing invariants in distant parts of the system.
Thirdly, Claude had perfect first-attempt results when tracing complex authentication state changes across multiple files.
However, this takes longer and costs more in tokens.
When risks are high, deep planning reduces the chance of spending days debugging.
You Can Also Check: Decoding Copilot Cost: The Ultimate 2026 AI Pricing And Tiers Guide
GPT-5.3 Codex is a quick and fast terminal-based model. Unlike Claude Opus 4.6, which is more of a careful architect, Codex gets stuck in file editing, live compiling, and fixing issues in the console.
This model excels in local desktop automation, bespoke dev environments, and Git branch environments. The practical benefits are:
The downside to this quick and speedy model is that it does not have a great architecture.
Because it uses Repo-RAG systems to pull information, it can struggle to understand constraints.
Furthermore, it can perfectly fix a function within the local environment but may completely break an implicit constraint in another folder.
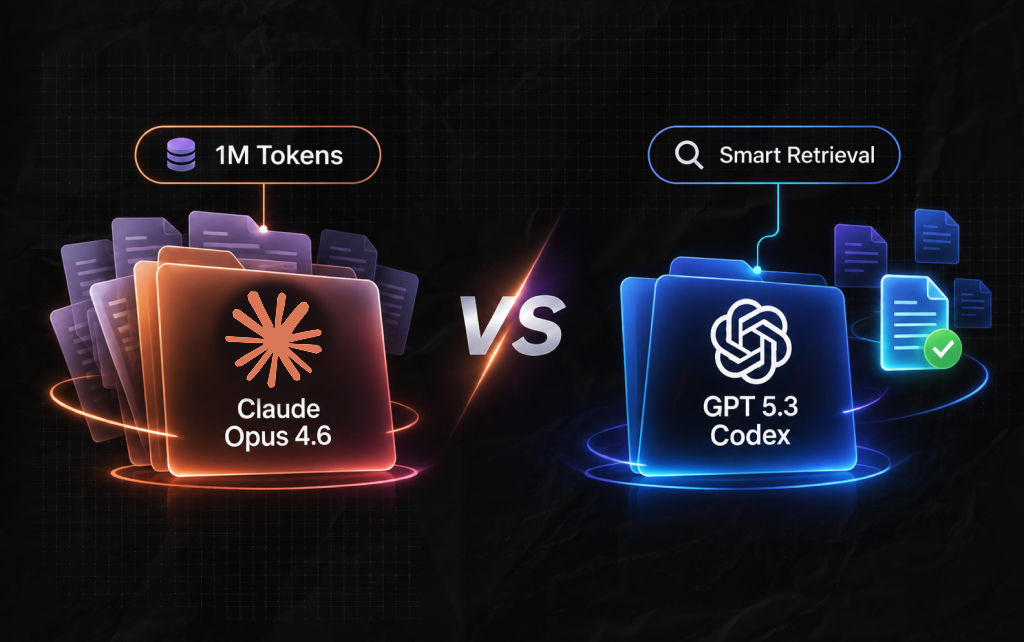
Understanding the fundamental mechanisms behind knowledge organization is key to this comparison between GPT 5.3 Codex vs Claude Opus 4.6.
Claude Opus 4.6 uses brute force. All modules in a group will be loaded into the prompt.
The system will always have the exact structure of everything in it.
This ensures nothing is forgotten when dealing with large-scale changes, such as porting parts of the code between React and Svelte.
Moreover, GPT-5.3 Codex uses intelligent retrieval. It only gets the necessary bits of code. This makes it very efficient in speed and cost.
However, if your engineering issue involves tracing complex dependencies across forty different files, it might not retrieve the file you need. This can result in an incomplete suggestion.
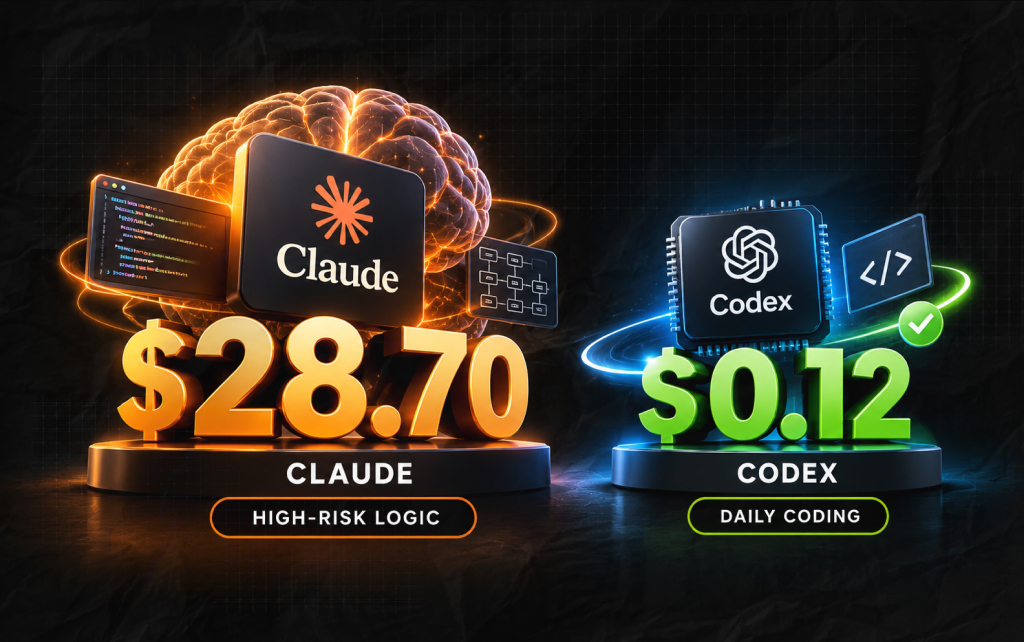
Even if you’re using an AI tool with a great technical spec, API costs will keep you from using it.
The cost difference between the two is huge. Anthropic charges $5.00 per million input tokens and $25.00 per million output tokens for their standard Opus 4.6 model.
If you’re doing large-scale multi-file analysis or using the 1M token beta tier, costs will rise quickly.
One developer recently did a case study showing a complex engineering task costing $28.70 in Claude pricing for deep reasoning.
When they ran a comparable implementation via the rival platform, the cost dropped sharply to just $0.12.
This is an extreme example. However, the structure-to-pricing ratio is key to know.
Moreover, it would be very inefficient to send low-level developer queries or basic syntax requests to an architectural model.
Use the high-cost model only for high-risk changes to your systems, since you don’t want to disrupt your core software pipelines.
Moreover, you can also use the faster and cheaper model for day-to-day operations.
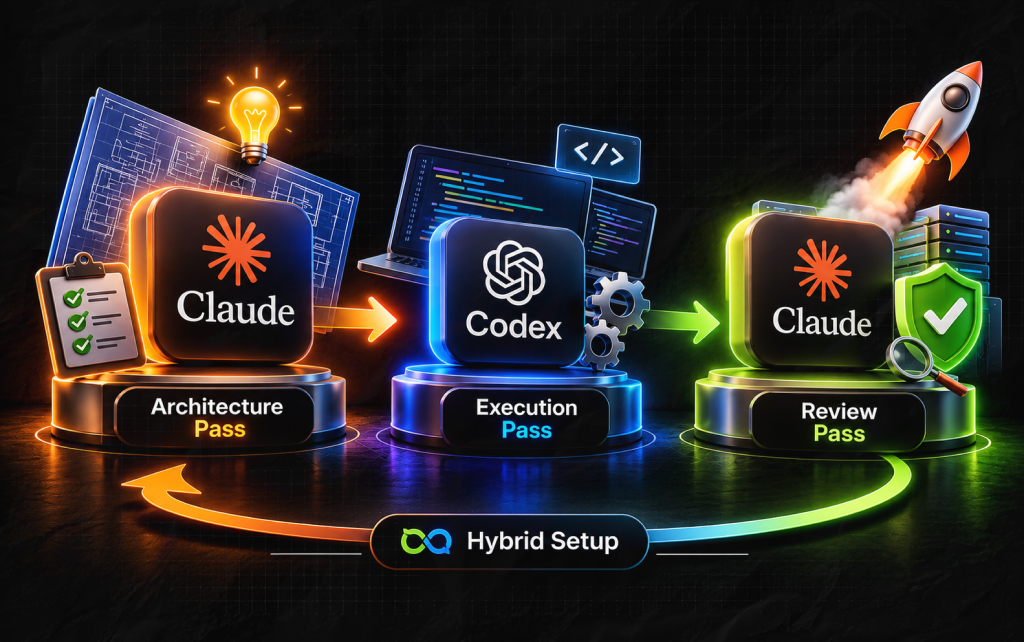
Engineering teams have had great success using both of these models in combination. You can combine the planning and execution to get the best of both worlds.
Feed your base logic prompt to Claude Opus 4.6 and ask it to give you a highly detailed breakdown of how to implement the feature.
And this includes interfaces and edge cases.
Feed this to GPT-5.3 Codex and restrict it to one step at a time.
Moreover, this means it will handle fast-moving terminal actions, test scripts, and compiler errors well.
Once your code has passed local testing, feed it into Claude Opus 4.6 to check your logic.
It has a detailed logic checker that can easily find bugs, access control issues, and security issues that quick models may miss.
Moreover, using multiple models can help avoid some of the issues of using just one agent.
So, you can harden your code features before deploying to the staging environment without paying a lot in API costs.
When deciding whether to use GPT 5.3 Codex vs Claude Opus 4.6 for your next sprint, use the following simple rules:
Use Claude Opus 4.6 if you’re starting brand-new complex apps, doing large-scale refactorings, or changing logic across many files.
On the other hand, use GPT-5.3 Codex if you’re doing lots of test scripts, debugging issues locally, or doing lots of terminal development.
Overall, the right model depends on what is causing problems in your workflow. A good engineering team will never be biased towards one model over another.
Instead, you’ll want to create a smart routing system that automatically chooses the right model for your specific problem.
Additional Resource: Glean AI Pricing For Enterprise Search 2026: The Comprehensive Buyer’s Guide
Piyasa is a search engine marketing strategist who has spent the last six years decoding Google's ever-changing mind. From corporate giants to neighborhood storefronts, she helps businesses cut through the digital noise and actually get noticed online. When she isn’t building SEO strategies or writing the latest search industry breakdowns for Search Engine Magazine, you can usually find her hanging out with friends - and gently reminding them that no, she cannot personally fix the latest algorithm update for them.
View all Posts
Glean AI Pricing For Enterprise Search 2026: ...
Oct 31, 2026
Decoding Copilot Cost: The Ultimate 2026 AI P...
Oct 31, 2026
Decoding Claude Pricing: A Friendly Guide To ...
Oct 31, 2026
The Ultimate Guide To Edit Code GDTJ45 Builde...
Oct 30, 2026
How To Create Linkable Assets That Earn Thous...
Oct 30, 2026